# Keep all indirect identifiers and one sensitive attribute (religion)
data_ana <- data_withoutdirectidentifiers %>%
select(id, plz, gender, age, income, years_in_job, education, religion)De-Associative Techniques
TipLearning Objectives
- Know selected de-associative techniques.
- Apply anatomization as one de-associative technique in R.
De-associative techniques protect privacy by breaking the link between indirect identifiers and sensitive variables, rather than altering the values themselves. The underlying idea is that even if an attacker can identify a person’s record based on their demographic attributes, they should not be able to learn their sensitive values from it.
NoteA Technique for Special Cases
De-associative techniques require a lot of effort: they are not available as ready-made functions in sdcMicro, so you have to implement them yourself, and the resulting data is harder to analyze. They are only rarely the best solution. In most cases, non-perturbative or perturbative techniques reach a similar level of privacy with far less work. I still cover de-associative techniques here, so you know they exist and can recognize the rare cases where they fit.
The simplest version of this is just separating a dataset into two tables—one with the identifiers and one with the sensitive attributes, and randomizing the order of rows in one of them. The problem is that this makes it impossible to link any demographic context to the sensitive values, which severely limits which analyses can be done. It is more of a last resort than a practical technique for sharing research data.
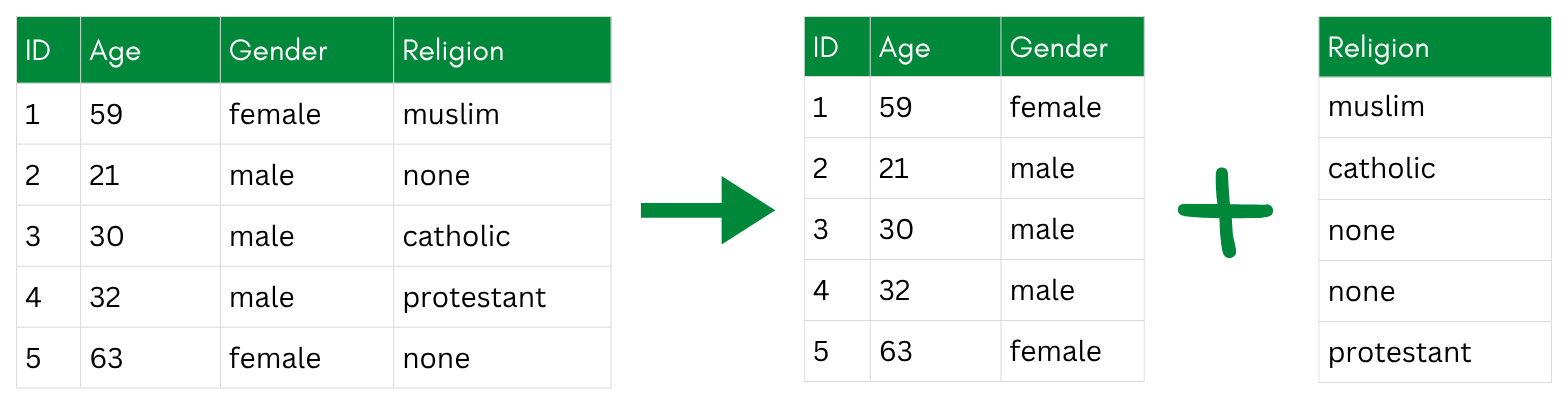
More useful are approaches that preserve some analytical structure while still breaking the individual-level link—the two main ones being bucketization and anatomization.
Examples of De-Associative Techniques
Bucketization
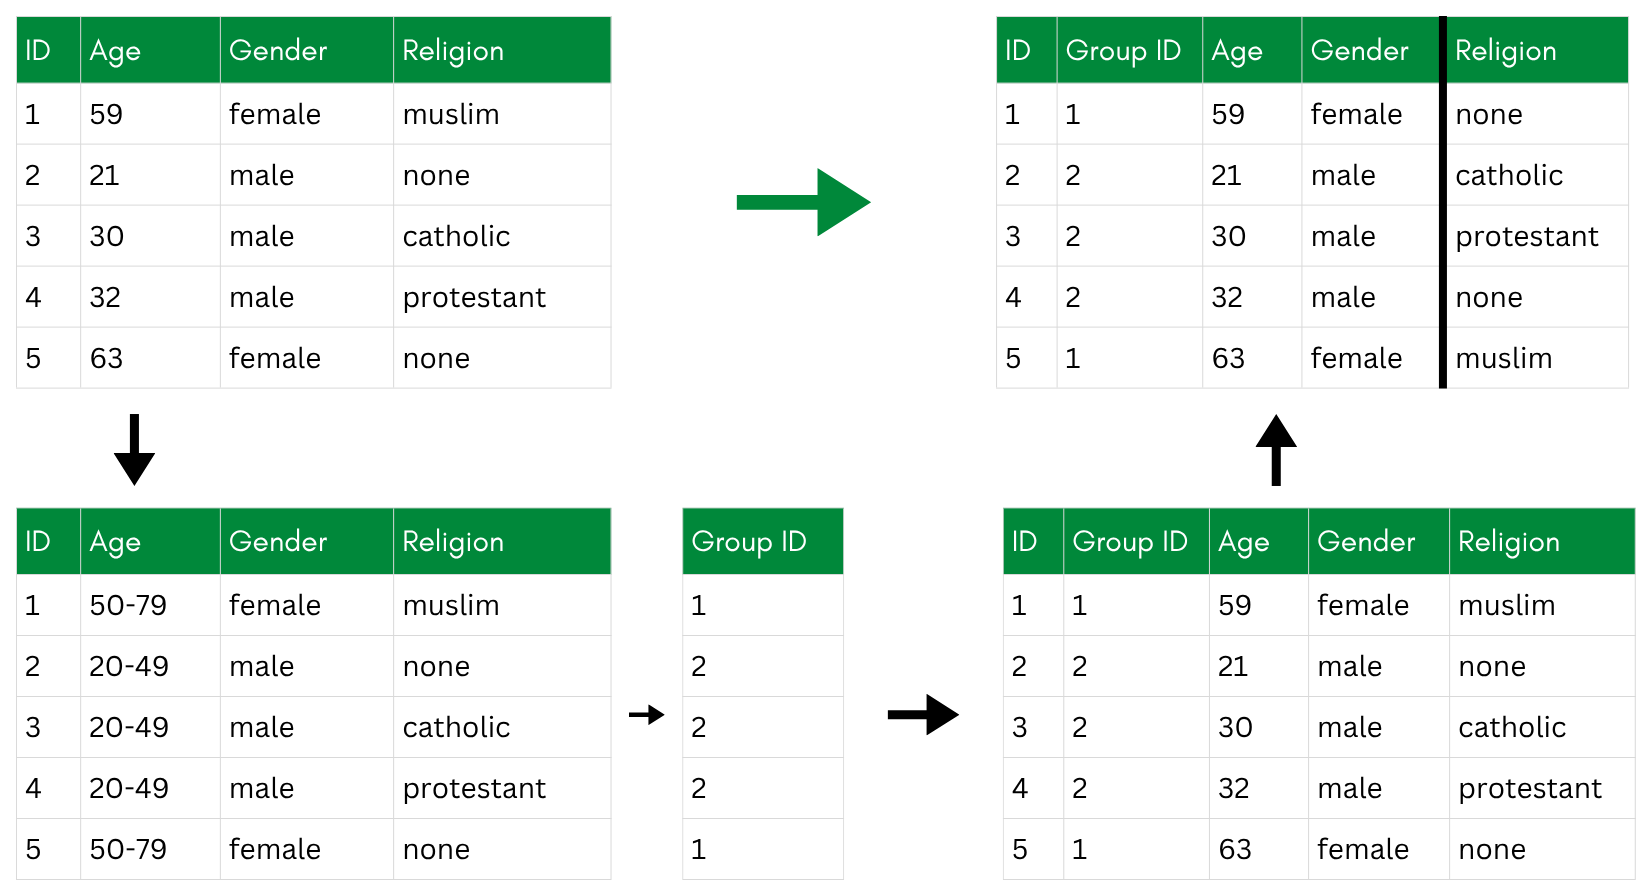
Bucketization groups records into “buckets” based on their indirect identifiers (like age, gender, or postal code), with each bucket required to contain at least k records to satisfy k-anonymity (Li and He 2023). Within each bucket, the sensitive values—such as income or political opinions—are randomly shuffled among the records. The result is that an attacker might be able to narrow someone down to a bucket, but cannot tell which sensitive value belongs to which specific person within it.
The process works in three steps:
- Generalize the indirect identifiers to create buckets.
- De-generalize the identifiers within each bucket back to their original values.
- Permute the sensitive values randomly within each bucket.
The shuffling in step 3 is what makes this a de-associative rather than a perturbative technique—the values themselves are unchanged, only the assignment between records and sensitive attributes is broken within each group.
Anatomization
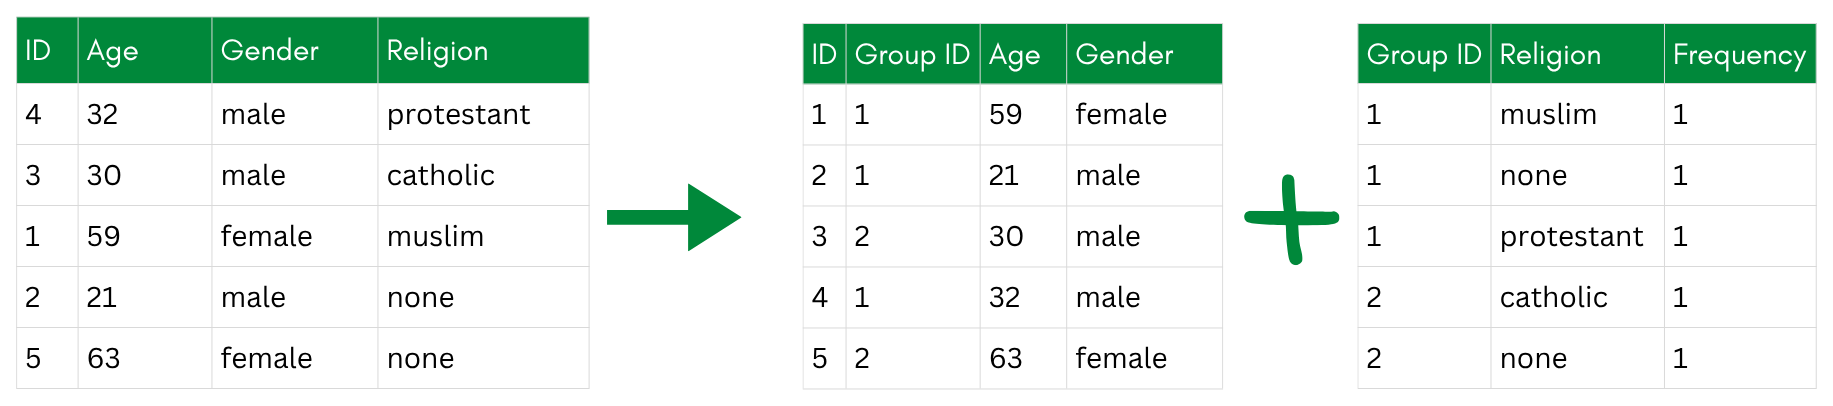
Anatomization is a cleaner alternative to bucketization that improves the properties of the resulting de-association (Xiao and Tao 2006). Rather than shuffling values within buckets, anatomization splits the dataset into two separate tables:
- A quasi-identifier table containing the indirect identifiers (e.g., age, gender, postal code), with a group ID linking each record to its group.
- A sensitive table containing the sensitive attributes and the same group ID, but with the individual record links removed. Instead of one row per person, it stores, for each group, how often each sensitive value occurs.
A researcher re-using the data can still answer questions like “what is the distribution of political opinions among 30- to 44-year-olds in postal region 8xxxx?” by joining on the group ID. But they cannot link any specific row in the sensitive table back to a specific individual in the quasi-identifier table as the association on the individual level is gone. Within a group, every sensitive value is equally plausible for every member.
Anatomization builds on bucketization but adds a guarantee: each group is deliberately constructed to be l-diverse—it contains at least l different sensitive values. This is what protects against attribute disclosure: even an attacker who pins down someone’s group still faces at least l competing possibilities for their sensitive value.
To build such groups, Xiao and Tao (2006) do not group records by similarity. Instead, they sort the records into one bucket per sensitive value, then repeatedly form a new group by drawing one record from each of the l currently-largest buckets. This spreads the most common values across as many groups as possible and keeps every group diverse.
NoteWhen Is Anatomization the Right Choice? (Almost Never)
Anatomization is a special-purpose technique. I wouldn’t recommend it as a default. Its main advantage is that it doesn’t distort any values: unlike non-perturbative techniques (which coarsen information of the indirect identifiers), perturbative techniques (which alter values), or synthetic data (which fabricates data), anatomization publishes only true values and destroys “just” the participant-level link between the indirect identifiers and the sensitive variable. This link is usually quite important, so only use the technique if all of these apply:
- the research question concerns the sensitive variable’s group-level distribution or associations instead of individual-level linkage, and you can accept the added imprecision (e.g., due to an overly large sample size);
- you specifically want to avoid changing any values that are kept; and
- identity disclosure is no concern, since anatomization leaves the indirect identifiers fully intact.
For most questions these conditions do not all hold, and a perturbative method or synthetic data is the more practical choice: easier to analyze (a single table), better supported by tools like sdcMicro, and protective of the identifiers too. This is the case for our example dataset, too. I still implement anatomization for that dataset below as an instructive example.
Pro and Contra of Using De-Associative Techniques
Pros:
- can be highly privacy-preserving
Cons:
- complex and not implemented as predefined functions within an R package
- a similar level of privacy can be reached by combining other techniques
- added level of complexity for analyses
Exercise: Applying Anatomization
Let’s implement anatomization step by step, following the algorithm proposed by Xiao and Tao (2006). It is not available in sdcMicro, so we will build it ourselves with a lot of data wrangling. The algorithm has 19 steps, but I will break them down into more workable chunks.
Because anatomization protects a sensitive attribute rather than the indirect identifiers, we work on a subset of the data that keeps all indirect identifiers plus one sensitive variable, religion. Working this algorithm for the combination of all sensitive attributes (including the political opinion items) is possible, but more complex. To keep it simple, I only focus on religion.
Our data does not really need this level of protection—I use it here purely for demonstration.
The algorithm needs one parameter: the target level of l-diversity. l-diversity strengthens k-anonymity—it requires that every group contains at least l different values of the sensitive attribute, so that locating someone’s group still leaves l competing possibilities for their sensitive value. I aim for l = 2.
l <- 2 # every group must contain at least 2 different religionsStep 1: Sort the Data Into Buckets
NoteBuckets vs. Groups
Throughout this exercise, I use both the terms “buckets” and “groups”:
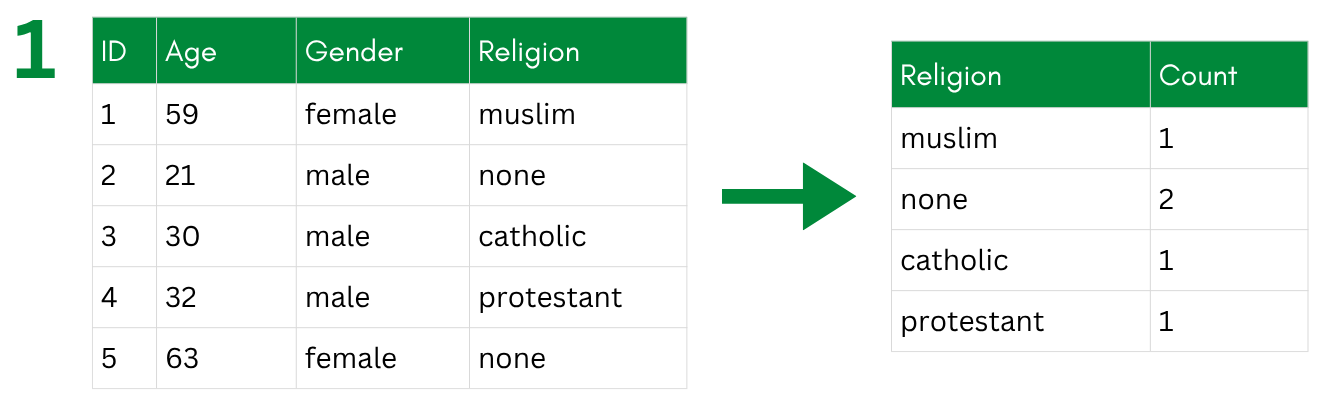
- A bucket collects all records that share the same sensitive value (e.g., one bucket per religion). These are the divisions we draw from within the algorithm.
- A group is a finished, l-diverse set of records (identified by a
group_id), built by taking one participant’s data from each of several different buckets.
To add to the confusion, this use of “bucket” differs from the bucketization technique above, where a bucket groups data by indirect identifiers. In anatomization, buckets are defined by the sensitive value instead.
Target: Get an overview of the buckets (one per religion) we will draw from later. To that end, create a character vector religions holding the distinct religion values, and a data frame bucket_sizes with the frequency of each religion.
NoteSolution
First, list all religion values that occur in the data. These define the buckets:
# All distinct values of the sensitive attribute
religions <- data_ana %>%
  distinct(religion) %>%
  pull(religion)

religions
[1] "Catholicism" "None" "Islam"
[4] "Protestantism" "Buddhism" "Judaism"
[7] "Eastern Orthodoxy"Now count how many records fall into each bucket:
# Bucket sizes, largest first
bucket_sizes <- data_ana %>%
  count(religion, sort = TRUE)

bucket_sizes
religion n
1 None 75
2 Catholicism 56
3 Protestantism 50
4 Islam 13
5 Buddhism 3
6 Judaism 2
7 Eastern Orthodoxy 1
TipEligibility Condition
A condition for anatomization to work is the eligibility condition. Anatomization can only place every record into an l-diverse group if no single religion is too common: the largest bucket (i.e., the most frequent religion) must not exceed n / l records; otherwise, the specific l-value cannot be fully reached.
Here, we can check that this is the case:
# Largest a bucket may be if I want to keep every record
n_total     <- nrow(data_ana)
max_allowed <- n_total / l

eligibility <- bucket_sizes %>%
  mutate(share        = n / n_total,
         within_limit = n <= max_allowed)
Here, with l = 2, no bucket exceeds the limit of 100 (= 200 / 2). So we can make the dataset 2-diverse.
If this were not the case (e.g., when choosing l = 3), there would be records left over. To still achieve the targeted l, we would then need to suppress selected values.
Intuitively, it may seem as if one repeated value wouldn’t cause a lot of harm. But l-diversity, as used here, is not simply about having l different values present. Following Xiao and Tao (2006), we use a rather strong, frequency-based definition: no single sensitive value may make up more than a 1/l share of a group. This is deliberately stricter than the common rule of distinct l-diversity, where at least l distinct values need to be present, under which one repeated value wouldn’t be an issue.
The stricter rule can protect against probabilistic inference attacks: l-diversity protects the sensitive value. In a group of three persons, two with religion none and one muslim, two different religions are present, so no one is uniquely identifiable. But an attacker who pins someone to this group would guess none and be right two out of three times (67%). That is well above the 1/l = 50% ceiling that 2-diversity is meant to guarantee. Formally, the most frequent value covers 2/3 of the group, and 2/3 > 1/l = 1/2, so the group is not 2-diverse.
This is also why the algorithm builds the smallest possible groups (here, exactly l = 2 records, each with a different religion): every value then appears exactly once, i.e., at a 1/l share, which both maximizes utility and keeps each group at the diversity limit.
Step 2: Build the l-Diverse Groups
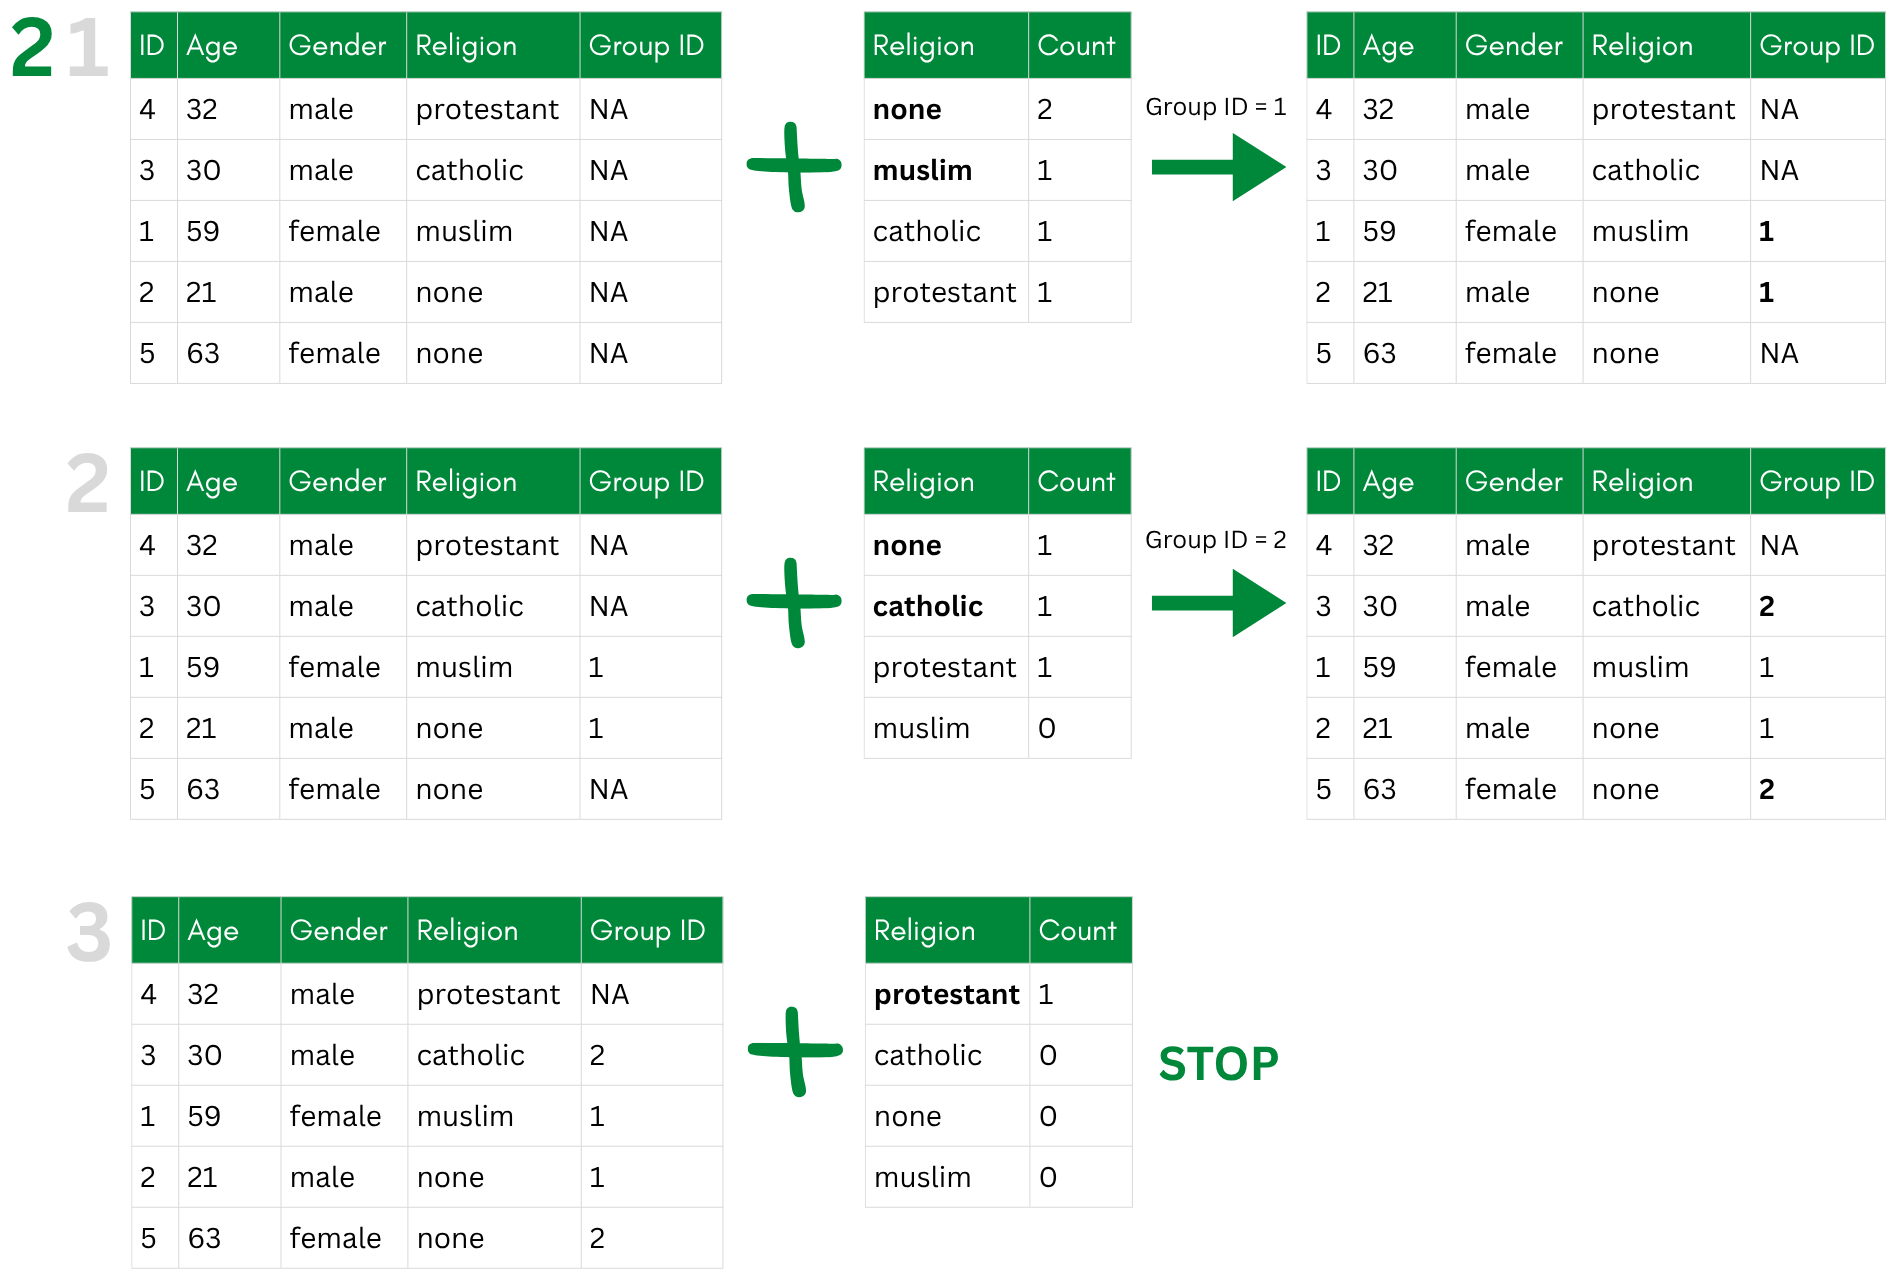
Target: Create a working data frame pool—a shuffled copy of data_ana with an added group_id column (empty in the beginning) and fill in group_id by repeatedly opening a new group and taking one record from each of the l currently-largest buckets, until fewer than l buckets still have records. Because each record in a group comes from a different bucket, every group automatically holds l different religions.
NoteSolution
Rather than juggling one data frame per bucket, I track group membership in a single new column, group_id. I shuffle the rows once up front so the groups don’t follow the original row order, and set a seed so the result is reproducible within this exercise. I could also, instead of shuffling at the beginning, pick random rows when assigning records to the groups; it is just important that the original order can’t be reverse-engineered by an attacker who knows the algorithm.
set.seed(2026) # to make the results reproducible within this exercise;
# delete for a real application (especially when publishing the script alongside the data)

# One working table; group_id is filled in as I assign records.
pool <- data_ana %>%
  slice_sample(prop = 1) %>%  # shuffle the rows once
  mutate(group_id = NA)       # NA = not yet assigned

next_group <- 0L

# Grouping: while at least l religions still have unassigned records, open a new group and take one record from each of the l currently-largest buckets.

repeat {
  # counts of still-unassigned records per religion, largest first
  remaining <- pool %>%
    filter(is.na(group_id)) %>%
    count(religion, sort = TRUE)

  # stop when fewer than l religions still have records
  if (nrow(remaining) < l) break

  next_group <- next_group + 1L

  # the l religions with the most remaining records
  top_religions <- remaining %>%
    slice_head(n = l) %>%
    pull(religion)

  # take exactly one still-unassigned record from each of those religions
  picks <- pool %>%
    filter(is.na(group_id), religion %in% top_religions) %>%
    group_by(religion) %>%
    slice_head(n = 1) %>%
    ungroup() %>%
    pull(id)

  # stamp those records with the new group id
  pool <- pool %>%
    mutate(group_id = if_else(id %in% picks, next_group, group_id))
}

next_group   # number of groups created
[1] 100Each pass draws from l different buckets, so every group we just built contains exactly l = 2 distinct religions.
In this case, all participants have been assigned to a group, without any leftovers in remaining. This is not naturally the case; oftentimes, the algorithm will leave you at this point with a few individuals that have not been assigned. For that case, you follow the third step:
Step 3: Handle the Leftover Records (Skip in Case of No Leftovers)
Target: Collect the still-unassigned records in a data frame leftovers, then update pool by slotting each leftover into an existing group that does not yet contain that religion value (e.g., a leftover record with religion none can be slotted into a group that does not contain any other records with religion none). Records that fit into no group are collected in suppressed_ids and dropped from pool.
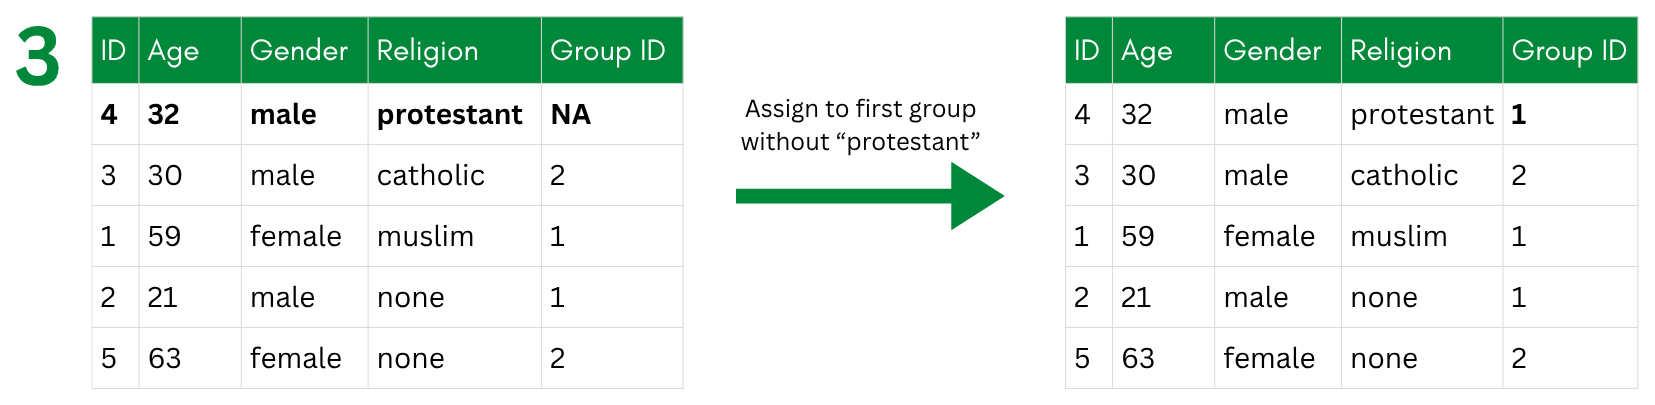
protestant record joins the first group without a protestant.
NoteSolution
Once fewer than l buckets remain, the loop in Step 2 stops with some records still unassigned. We handle them here.
You then try to slot each remaining participant into a group that has no one with the same sensitive value yet (so the group stays diverse, see the eligibility condition above). If no such group exists, the record cannot be released safely and has to be suppressed.
suppressed_ids <- integer(0)

for (rec_id in leftovers$id) {
  # this record's religion
  rel <- pool %>%
    filter(id == rec_id) %>%
    pull(religion)

  # existing groups that do NOT yet contain this religion
  open_groups <- pool %>%
    filter(!is.na(group_id)) %>%
    group_by(group_id) %>%
    summarise(has_rel = any(religion == rel), .groups = "drop") %>%
    filter(!has_rel) %>%
    pull(group_id)

  if (length(open_groups) > 0) {
    # place it in the first eligible group
    pool <- pool %>%
      mutate(group_id = if_else(id == rec_id, open_groups[1], group_id))
  } else {
    # nowhere safe to put it → mark for suppression
    suppressed_ids <- c(suppressed_ids, rec_id)
  }
}

length(suppressed_ids)   # how many records had to be dropped

# Drop the suppressed records
pool <- pool %>%
  filter(!(id %in% suppressed_ids))
In the last step, we split this one dataframe pool into two dataframes, the anatomized tables.
Step 4: Split Into the Two Anatomized Tables
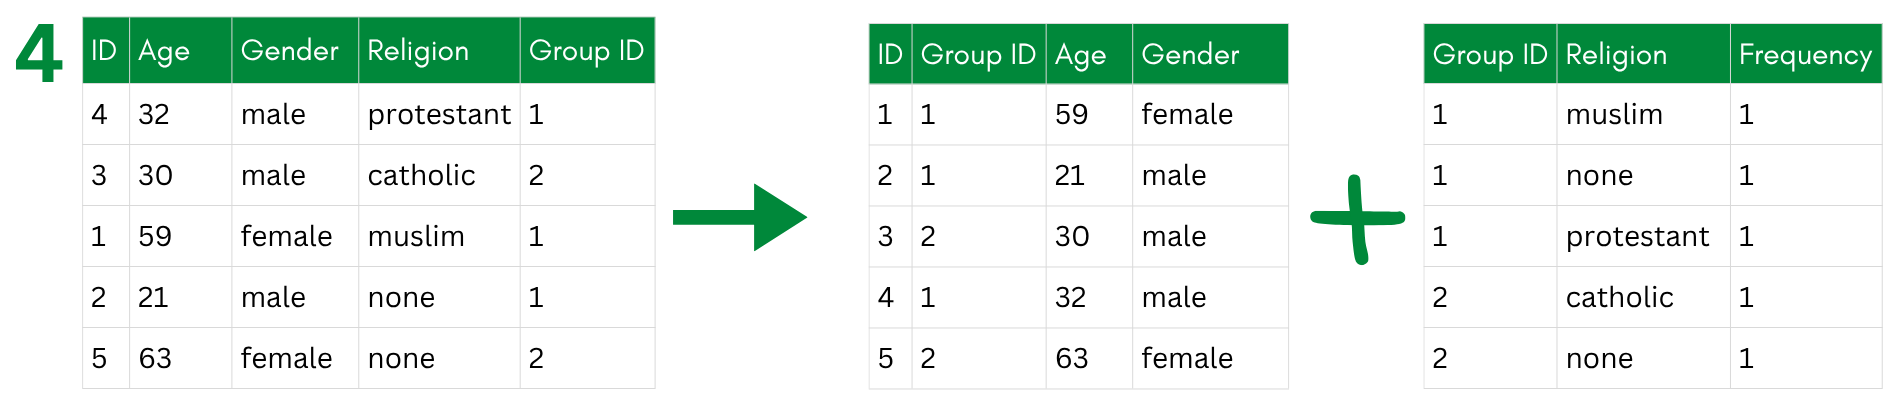
Target: Split pool into two data frames: ii_table, the indirect-identifier table (id, group_id, and all indirect identifiers, but no religion), and sensitive_table, the sensitive table (group_id, religion, and a per-group count, with no identifiers).
NoteSolution
# Indirect identifiers table: indirect identifiers + group id, NO religion.
ii_table <- pool %>%
  select(id, group_id, plz, gender, age, income, years_in_job, education) %>%
  arrange(group_id, id)

# Sensitive table: for each group, which religions occur and how often.
sensitive_table <- pool %>%
  count(group_id, religion, name = "count") %>%
  arrange(group_id, religion)

head(ii_table)
id group_id plz gender age income years_in_job education
1 38 1 80799 female 18 58538.33 1 high school
2 45 1 79793 male 22 36923.45 5 doctoral title
3 108 2 1587 male 61 9709.52 5 trade school
4 164 2 47226 female 57 63828.73 10 high school
5 44 3 53773 male 49 44352.87 0 high school
6 176 3 49429 female 22 38736.53 5 high schoolhead(sensitive_table) group_id religion count
1 1 Catholicism 1
2 1 None 1
3 2 Catholicism 1
4 2 None 1
5 3 Catholicism 1
6 3 None 1The only thing the two tables share is group_id. Neither table on its own—and no join between them—reveals which religion belongs to which person.
A researcher can still study group-level patterns—for example, the religion distribution across age bands—by joining on group_id. But the individual link between a person and their religion is broken.
If this was the technique you would use for your dataset, you would save the two dataframes now and publish them like this, potentially with additional measures in place. Note that having two datasets complicates the analysis process. In this tutorial, we will, however, not use this further and instead resume with the data as anonymized within the sdcObjects sdc_noise and sdc_micro in the last chapter on perturbative techniques.
Resources, Links, Examples
- See Carvalho et al. (2023) for more de-associative techniques.
- The anatomization algorithm we implemented here was introduced by Xiao & Tao (2006), Anatomy: Simple and Effective Privacy Preservation. See their paper for more technical details.
- For more on l-diversity and t-closeness, see this practical tutorial by Utrecht University.
References
Carvalho, Tânia, Nuno Moniz, Pedro Faria, and Luís Antunes. 2023. “Survey on Privacy-Preserving Techniques for Microdata Publication.” ACM Computing Surveys 55 (14s): 1–42. https://doi.org/10.1145/3588765.
Li, Boyu, and Kun He. 2023. “Local Generalization and Bucketization Technique for Personalized Privacy Preservation.” Journal of King Saud University - Computer and Information Sciences 35 (1): 393–404. https://doi.org/10.1016/j.jksuci.2022.12.008.
Xiao, Xiaokui, and Yufei Tao. 2006. “Anatomy: Simple and Effective Privacy Preservation.” VLBD ’06, September 12. https://dl.acm.org/doi/10.5555/1182635.1164141.